


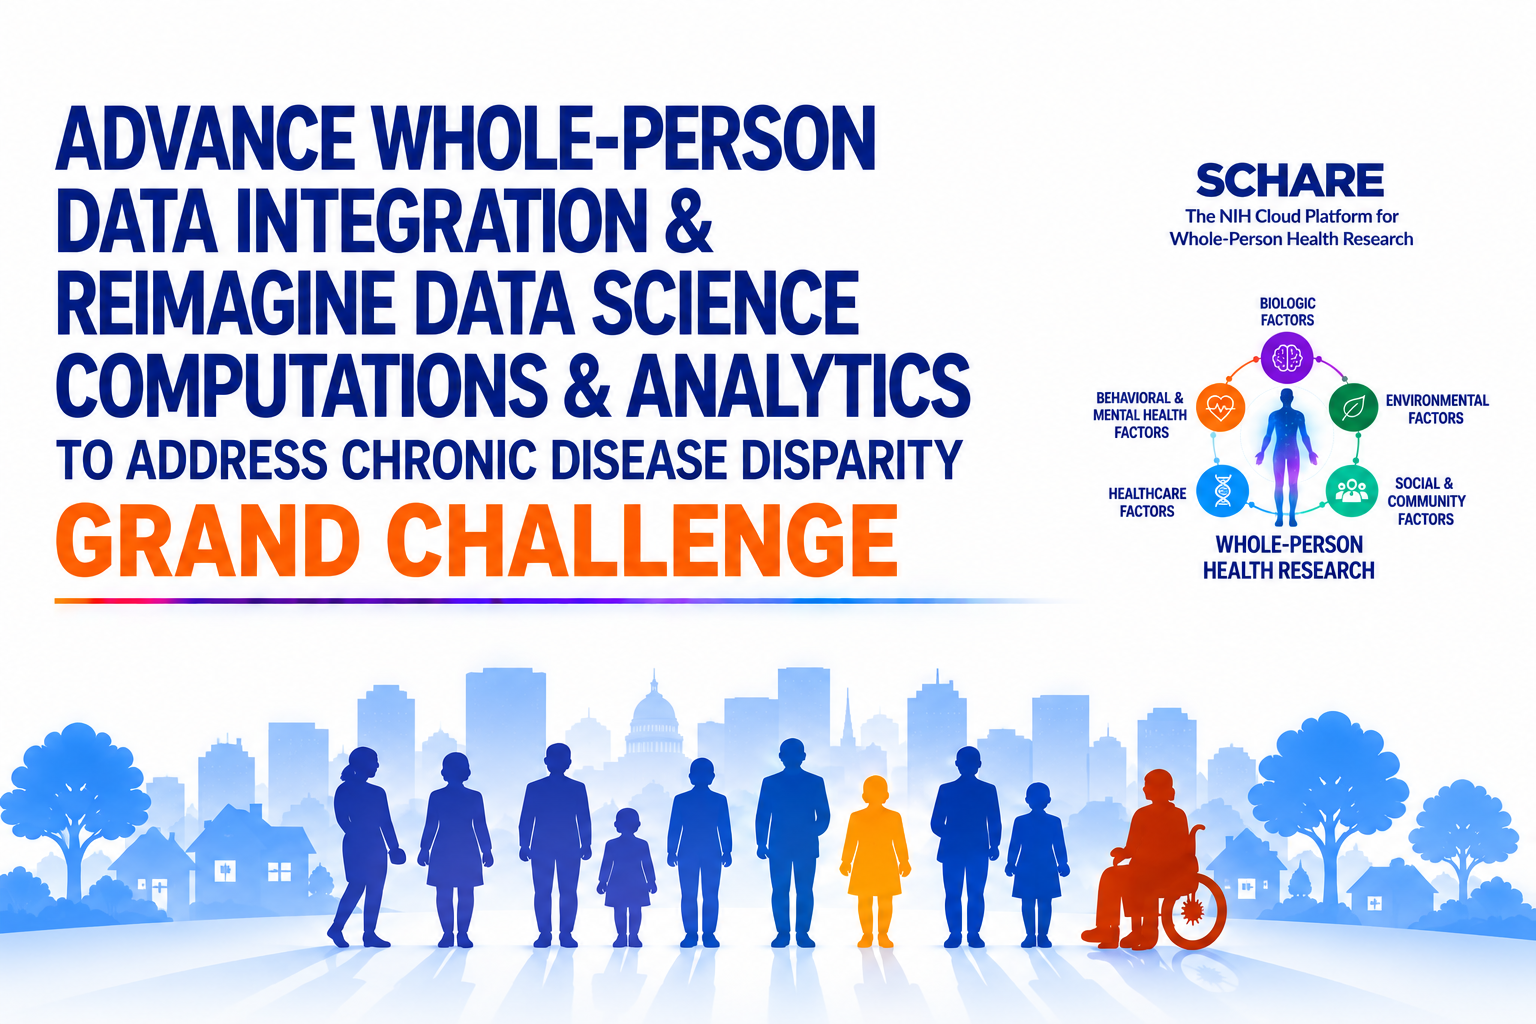
This Grand Challenge seeks to prepare big data for AI health disparities research that addresses chronic disease(s). It is imperative that the data be tested for representation of the populations and other fit-for-purpose features it will address. The deliverable must be accessible to other researchers.
The Challenge will be conducted in 3 phases, and only the winners of each Phase are eligible to compete in the next Phase (i.e., only Phase I winners may compete in Phase II, and only Phase II winners may compete in Phase III).
Challenge Launch: September 21, 2026
Phase 1 Deadline, January 22, 2027
Total cash prizes: $1,000,000
OVERVIEW
Challenge Statement
Despite unprecedented growth in biomedical, clinical, behavioral, environmental, and community data, researchers still lack the computational infrastructure needed to integrate these diverse data into a unified, AI-ready ecosystem capable of advancing whole-person chronic disease research. Today's fragmented data systems limit our ability to understand how biological, behavioral, environmental, healthcare, and place-based factors interact across the lifespan to influence disease risk, progression, treatment response, and outcomes.
The SCHARE Grand Challenge invites multidisciplinary teams to reimagine data science computations, analytics, and interoperable data ecosystems that transform fragmented data into reusable, AI-ready research resources. Participants will develop innovative methods for integrating diverse data sources, overcoming missing and underrepresented data, improving interoperability, and creating scalable computational frameworks that accelerate discovery of actionable insights for chronic disease prevention, precision treatment, and improved population health.
Rather than creating another isolated dataset, participants will build reusable infrastructure that enables researchers to ask—and answer—the next generation of whole-person health research questions. To enable AI‑driven whole‑person chronic disease research needs, data sets need to be created that integrate AI across health, education, social sciences, and other domains to understand and support individuals holistically.
Many populations most affected by chronic disease disparities are challenged in biomedical research analyses because of:
- Small sample sizes
- Missing data
- Inconsistent data collection
- Privacy concerns
- Limited longitudinal follow-up
- Incomplete linkage between clinical and non-medical drivers of health data
Data collection is not the only paucity. Intelligent data optimization and data science methodologies need enhancements and reimagined to provide reliable devices, tools, technologies, and data aggregation of mixed data types. This challenge will emphasize methodological innovation that addresses inconsistent and missing data more visible, analyzable and actionable in research. Some strategies known to be considered are Bayesian hierarchical models, few-shot learning, privacy preserving synthetic data generation, data augmentation, multiple imputation, probabilistic graphical models, deep imputation, causal missing-data methods, uncertainty-aware modeling, longitudinal simulation, survival modeling, trajectory forecasting, synthetic cohort expansion, agent-based simulation, anomaly detection, and transfer learning, However, these strategies can have limitations. In addition, there are limited strategies for assessing synergistic effects over time regarding the contextual dynamic factors regarding non-medical drivers of health’s impact on biologics. Consequently, this Challenge’s focus on data aggregation and methodologies that support whole-person health assessments to improve health outcomes and to reduce health disparities. Interoperability strategies, including agent to agent, APIs MCPs etc. are encouraged for data aggregation across platforms.
Participants will leverage SCHARE and other interoperable research data ecosystems to develop scalable, trustworthy, and actionable solutions that accelerate discovery, device development, intervention design, and precision public health. The intent is to catalyze a paradigm shift in health disparities research from describing disparities and identifying correlations toward discovering the underlying biological, behavioral, environmental, social, and healthcare drivers of disease across the lifespan. Through advanced data science methodologies, the Challenge seeks to identify actionable intervention targets and develop solutions that mitigate these health disparity metrics:
- Greater Incidence and/or prevalence of preclinical disease/biomarker or clinical diseases/disorders/conditions
- Higher rates of disability adjusted life years or prevalence of short-term and/or long-term preventable complications
- Earlier onset of disease/disorders/conditions
- Higher prevalence of modifiable risks, health risk behaviors, & adverse clinical outcomes
- Premature or excessive morbidity and mortality from specific conditions
- Lower rates of life expectancy, health-related quality of life, and/or daily functioning in physical, cognitive, or socio-emotional domains
- Variations in the access, utilization, availability and/or quality health care
Scientific Challenge
Primary Goal: Build the Data Infrastructure and Analytics for AI-Driven Whole‑Person Chronic Disease Health Disparity Research
Develop integrated AI ready data set(s), innovative computational methods, interoperable data resources, and AI-ready analytical frameworks that improve whole-person chronic disease research by integrating biological, behavioral, environmental, healthcare, and community data into scalable research infrastructure applicable to populations impacted by chronic disease health disparities.
Three Phase Objectives
Design an innovative concept blueprint for creating AI-ready whole-person datasets and the computational methods needed to integrate, harmonize, optimize, and transform diverse data into reusable research infrastructure for chronic disease disparities research. Participants should propose novel approaches for combining biological, behavioral, environmental, healthcare, community, and other relevant data into fit-for-purpose, interoperable, AI-ready datasets that support transparent, reproducible, and scalable AI and data science applications. The goal is to reimagine how diverse health-related data can be aggregated, integrated, analyzed, and translated into actionable knowledge that improves understanding of chronic disease disparities and informs future prevention, treatment, and public health strategies. These resources should be readily available for researchers to use to conduct AI driven research.
Concepts should demonstrate how advanced computational methods to capture the effects of dynamic variables, metadata standards, common data elements, interoperability strategies, feature engineering, and data quality optimization will improve dataset readiness for AI while enabling researchers to investigate complex whole-person interactions, uncover mechanistic pathways, and accelerate discovery in chronic disease research. Data sets to consider incapsulating whole-person health include:
Biological Factors, such as:
- Multi-omic data integration
- Genomics
- Proteomics
- Multi-omics
- Biomarkers
- Clinical measures
- Physiological monitoring
- Imaging
Non-Medical Drivers of Health, such as:
- Housing stability
- Food access
- Education
- Employment
- Transportation
- Social connectedness or isolation
- Environmental exposures
- Neighborhood characteristics
- Digital access
- Healthcare access and utilization
- Clinical and EHR data
- Behavioral data
- Environmental exposures
- Non-medical drivers of health or contextual factors
- Healthcare access and utilization
- Community-level and geospatial factors
Concept should include the description of information, such as:
- The scientific problem
- Whole-person data sets with sources, including SCHARE
- Interoperability strategy
- Computational innovations
- AI-readiness strategy
- Population representation strategy
- Missing-data and/or small sample sizes strategy(ies)
- Potential impact on chronic disease research
- Use of APIs or MCPs
The purpose of Phase II is to transform the approved Phase I concept into a functional prototype that demonstrates AI-ready datasets, innovative computational methods, and interoperable workflows for whole-person chronic disease research. Participants will build, test, and document reusable tools, computational pipelines, and analytical resources that enable researchers to integrate diverse data sources, discover mechanistic pathways, and prepare datasets for artificial intelligence applications. The prototype should demonstrate scientific innovation, technical feasibility, interoperability, scalability, and usability within the SCHARE ecosystem and/or other compatible research environments.
Objectives
- Objective 1: Develop a working prototype that creates AI-ready, whole-person datasets by integrating biological, clinical, behavioral, environmental, healthcare, community, and other relevant data sources.
- Objective 2: Develop and demonstrate interoperable computational workflows that automate data ingestion, harmonization, transformation, feature engineering, metadata generation, and AI-ready dataset preparation.
- Objective 3: Develop innovative computational methods that improve understanding of mechanistic pathways contributing to chronic disease by integrating diverse whole-person data.
- Examples include:
- causal discovery
- graph analytics
- multimodal learning
- digital twins
- synthetic data
- temporal modeling
- Bayesian modeling
- agent-based simulation
- foundation models
- Objective 4: Develop reusable computational resources, visualization tools, dashboards, APIs, notebooks, or software that can be adopted by the broader research community.
- Objective 5: Demonstrate that the prototype produces transparent, reproducible, scalable, and AI-ready research infrastructure capable of supporting future model development and intervention research.
The purpose of Phase III is to validate the AI-ready datasets, computational methods, interoperable workflows, and research infrastructure developed in Phases I and II improve AI-driven whole-person chronic disease research. Participants will demonstrate that their prototype supports robust, reproducible, generalizable, and interpretable AI applications, while uncovering mechanistic pathways, identifying actionable intervention opportunities, and generating reusable resources for the broader scientific community. Successful projects will show that the infrastructure not only improves model performance but also enables new scientific discoveries that would not have been possible using conventional datasets or analytic approaches.
Objectives
- Objective 1: Validate that the AI-ready datasets and computational infrastructure support accurate, reproducible, and scalable AI models for chronic disease research.
- Objective 2: Evaluate whether the integrated whole-person datasets improve identification of mechanistic pathways associated with chronic disease onset, progression, complications, treatment response, and prevention.
- Objective 3: Demonstrate that innovative computational methods improve scientific discovery beyond existing approaches.
- Objective 4: Evaluate the generalizability, robustness, fairness, transparency, and reproducibility of AI models across diverse populations, settings, and chronic diseases.
- Objective 5: Demonstrate reusable decision-support tools, dashboards, computational libraries, APIs, and workflows that enable other investigators to conduct AI-driven whole-person research.
- Objective 6: Provide all documentation and source code for validation and reproducibility.
VISION
By the end of the Grand Challenge, participants will have developed the next generation of whole-person data science infrastructure—reusable computational tools, interoperable datasets, and AI-ready workflows that enable researchers to move beyond describing chronic disease disparities toward discovering actionable mechanisms, evaluating interventions, and accelerating precision prevention and treatment.
PRIZES
Total cash prizes
$1,000,000
Prize Description
The Challenge will be conducted in 3 phases, and only the winners of each Phase are eligible to compete in the next Phase (i.e., only Phase I winners may compete in Phase II, and only Phase II winners may compete in Phase III):
- Phase I--IMAGINE: Design The Data Set And Computational Ecosystem
- $10,000 per winner up to 10 winners.
- Phase II--BUILD: Create A Working Prototype And Interoperable Workflows
- $100,000 per winner up to 4 winners.
- Phase III--PROVE: Validates that the data set and model infrastructure improves scientific discovery and enables new AI-driven chronic disease disparities research.
- First Place: $275,000
- Second Place: $225,000
TIMELINE
Challenge Launch: September 21, 2026
Registration Deadline: November 23, 2026
- Phase I
- Submission Open: September 25, 2026
- Submission End: January 22, 2027
- Winners Announced: March 1, 2027
- Phase II
- Submission Open: March 2, 2027
- Submission End: July 9, 2027
- Winners Announced: August 13, 2027
- Phase III
- Submission Open: August 16, 2027
- Submission End: November 19, 2027
- Winners Announced: December 20, 2027
JUDGING
Only projects that use data science strategies data integration and population computation models to address whole person (exposome) chronic disease health disparity will be considered for this Challenge. Prefer to include the use of SCHARE data sets and resources..
| Evaluation Components | Points |
|---|---|
| Overview and Scientific Vision | 15 |
| Investigation Team Qualifications | 15 |
| Whole Person Data Science Framework | 35 |
| AI ready data sets development plan | |
| Whole-person data integration Architecture | |
| Computational Innovation Plan | |
| AI Readiness and Mechanistic Discovery Framework | 25 |
| AI Readiness Assessment Framework | |
| Mechanistic Discovery Strategy | |
| Impact Statement and Reusable Research Resource Plan | 10 |
| Total | 100 |
Overview and Scientific Vision (15 Points)
Review Criteria - Reviewers will assess:
- Importance of the chronic disease challenge
- Clarity of the research questions
- Appropriateness of the intended AI applications
- Integration of a whole-person health framework
- Representation of populations and applicability of the proposed research
- Novelty of the proposed computational or data science approach
- Potential to significantly advance chronic disease research
Outstanding submissions will clearly articulate a compelling scientific vision and demonstrate how the proposed concept addresses an important unmet need through innovative AI-enabled approaches for whole person chronic disease disparities.
Investigator, Team, or Entity Qualifications (15 Points)
Review Criteria -Reviewers will evaluate:
- Demonstrated experience relevant to the proposed work
- Complementary expertise across team members
- Experience with data aggregation, harmonization and interoperability across data platforms
- Experience with AI, machine learning, data science, cloud computing, or biomedical informatics
- Expertise in chronic disease and/or health disparities research
- Experience integrating diverse data sources, addressing small sample sizes and missing data
- Evidence of successful multidisciplinary collaboration
- Defined roles and contributions of each team member
- Organizational capacity to complete the proposed work
Whole Person Data Science Framework (35 Points)
Projects should demonstrate a clear plan for creating interoperable, reusable, transparent, and fit-for-purpose datasets suitable for AI applications. Higher scores will be awarded to architectures demonstrating seamless integration across multiple domains while supporting future expansion and reuse. Projects should clearly demonstrate how the proposed computational innovations advance the current state of the science to generate knowledge regarding the mitigation of chronic disease disparities.
AI-Ready Dataset Development Plan
Review Criteria - Reviewers will assess the quality and feasibility of the proposed strategy for developing AI-ready datasets, including:
- Selection and justification of data sets and reliable sources
- Data integration and harmonization strategy
- Metadata standards
- Common data elements
- Data quality assessment plan
- Missing-data strategy
- Small sample size strategy
- Population representation strategy
- Feature engineering approach
- Data governance and provenance
- AI readiness evaluation strategy for model development
Whole-Person Data Integration Architecture
Review Criteria - Reviewers will evaluate:
- Completeness of the conceptual architecture
- Integration of biological, clinical, behavioral, environmental, community, and other relevant data
- Inclusion of non-medical drivers of health
- Data interoperability strategy
- Data flow architecture
- Scalability of the proposed framework
- Use of SCHARE datasets or infrastructure, when appropriate
Computational Innovation Plan
Review Criteria - Reviewers will assess:
- Novelty of the computational methods
- Appropriateness of the proposed analytical approaches
- Advancement beyond current methods
- Explainability and transparency
- Scalability
- Potential for reuse by other investigators
AI Readiness and Mechanistic Discovery Framework (25 Points)
Higher scores will be awarded to projects proposing objective, transparent, and reproducible methods for evaluating AI readiness. Preference will be given to approaches that move beyond descriptive analyses toward identifying actionable mechanisms and intervention opportunities.
AI Readiness Assessment Framework
Review Criteria - Reviewers will evaluate whether the proposed framework provides a comprehensive and measurable approach for assessing AI readiness, including these exampled features:
- Data completeness
- Data quality
- Interoperability
- Population representation
- Bias assessment
- Feature usability
- Metadata completeness
- Provenance
- Reproducibility
- Fitness for intended AI applications
Mechanistic Discovery Strategy
Review Criteria - Reviewers will evaluate how well the proposed integrated datasets and computational methods support identification of mechanistic pathways contributing to chronic disease, including such elements as:
- Biological mechanisms
- Behavioral mechanisms
- Environmental mechanisms
- Place-based mechanisms
- Lived experience mechanisms
- Healthcare-related mechanisms
- Community-level mechanisms
- Interactions among these domains
- Timing and temporal relationships among these factors
Impact Statement and Reusable Research Resource Plan (10 Points)
The strongest proposals will demonstrate the potential to transform research practices beyond the scope of a single project and to offer significant impact on understanding chronic disease disparities.
Impact Statement
Review Criteria - Reviewers will assess the potential for the proposed innovation to:
- Accelerate chronic disease research
- Advance whole-person health research
- Improve AI-enabled discovery
- Increase interoperability
- Improve reproducibility
- Enable future intervention development
- Produce resources with broad scientific value
Reusable Research Resource Plan
Review Criteria - Reviewers will evaluate the potential for the proposed work to produce reusable community resources, examples include:
- AI-ready datasets
- Data harmonization workflows
- Data integration tools
- Computational pipelines
- Interactive dashboards
- APIs and Model Context Protocol (MCP) interfaces
- Python or R libraries
- Notebook collections
- Visualization tools
- Metadata templates
- SCHARE-ready resources
| Evaluation Components | Points |
|---|---|
| Prototype Functionality and Technical Performance | 20 |
| AI-Ready Dataset Development | 15 |
| Interoperability and Workflow Design | 15 |
| Computational Innovation and Mechanistic Discovery Capability | 30 |
| Research Utility, Reusability, and Implementation | 20 |
| Total | 100 |
The ultimate goal is not simply to create a technically sound product, but to deliver usable, reusable, and sustainable research infrastructure that can be broadly adopted through SCHARE and by the wider biomedical, behavioral, healthcare, and public health research communities.
Prototype Functionality and Technical Performance (20 Points)
Review Criteria: Reviewers will evaluate aspects, such as:
- prototype maturity
- functionality
- usability
- technical quality
- successful demonstration
- stability
- performance
AI-Ready Dataset Development (15 Points)
Review Criteria: Reviewers will assess aspects, such as:
- interoperability
- metadata
- data quality
- provenance
- common data elements
- feature engineering
- population representation
- AI readiness
- reproducibility
Interoperability and Workflow Design (15 Points)
Review Criteria: Reviewers will evaluate such aspects as:
- workflow automation
- interoperability across platforms
- data harmonization
- metadata integration
- reusable workflows
- standards compliance
- SCHARE compatibility
Computational Innovation and Mechanistic Discovery Capability (30 Points)
Projects should demonstrate movement from descriptive analyses toward causal understanding and actionable insights. These features should address the dynamic synergistic or antagonistic relationship of whole person health.
Computational Innovation
Review Criteria: Reviewers will assess:
- originality
- computational sophistication
- advancement beyond current methods
- explainability
- scalability
- transparency
Mechanistic Discovery Capability
Review Criteria: Reviewers will evaluate whether the prototype can identify:
- biological pathways
- behavioral pathways
- environmental pathways
- place-based pathways
- contextual social influences
- healthcare-related pathways
- community interactions
- temporal relationships
- potential intervention targets
Research Utility, Reusability, and Implementation (20 points)
Review Criteria: Preference will be given to reusable, open, modular resources.
Reusable Research Resources
Reviewers will assess possibilities, such as:
- dashboards
- APIs
- computational libraries
- notebook collections
- software
- reusable workflows
- MCP services
- Notebooks
- Workflow templates
- Docker containers
- Cloud workflows
- metadata templates
- SCHARE-ready resources
Visualization, Dashboards, and User Experience
Reviewers will evaluate possibilities, such as:
- usability
- intuitive design
- scientific visualization
- researcher accessibility
- decision-support capability
Scalability, Reproducibility, and Documentation
Reviewers will evaluate key aspects, such as:
- documentation quality
- reproducibility
- portability
- scalability
- technical transparency
- ease of implementation
| Evaluation Components | Points |
|---|---|
| AI Model Performance and Validation | 20 |
| Scientific Discovery and Mechanistic Insights | 20 |
| Generalizability and Population Performance | 20 |
| Computational Innovation, Transparency and Trust | 20 |
| Research Translation, Utility, and Scientific Impact | 20 |
| Total | 100 |
Projects should demonstrate that AI-ready datasets improve model performance compared with existing approaches. Each should clearly demonstrate movement from prediction to mechanistic understanding.
AI Model Performance and Validation (20 Points)
Review Criteria: Reviewers will evaluate exampled features, such as:
- Advances understanding of chronic disease beyond prediction alone- examples
- Modifiable risk factors
- Prevention opportunities
- Treatment-response phenotypes
- Intervention targets
- Community intervention priorities
- Population-specific prevention strategies
- Model accuracy
- External validation
- Robustness
- Reproducibility
- Calibration
- Computational efficiency
- Data quality metrics
- Processing time
- Scalability testing
- Interoperability testing
- Reproducibility testing
- Benchmark comparisons
- User testing (if applicable)
- Advances understanding of chronic disease beyond prediction alone- examples
Scientific Discovery and Mechanistic Insights (20 Points)
Review Criteria: Reviewers will evaluate whether the project:
- Identifies previously unrecognized mechanistic pathways – biological, behavioral, environmental, social, etc.
- Temporal or long-term interactions
- Synergistic or antagonistic effects
- Integrates biological and non-medical drivers of health, including multi-domain
- Demonstrates temporal and multi-domain interactions
- Identifies actionable intervention targets
Generalizability and Population Performance (20 Points)
Review Criteria: Reviewers will assess:
- External validation
- Population representation
- Performance across diverse populations
- Adaptability to different diseases
- Robustness across healthcare settings
- Scalability
Computational Innovation, Transparency and Trust (20 Points)
Review Criteria: Reviewers will evaluate:
Responsible AI and Model Transparency -
- Explainability
- Bias assessment
- Reproducibility
- Uncertainty quantification
- Documentation
- Model interpretability
- Privacy protection
Computational Innovation
- Novel computational methods
- Advancement beyond existing approaches
- Scalability
- Efficiency
- Reusability
Research Translation, Utility, and Scientific Impact (20 Points)
Preference will be given to open, modular, and interoperable infrastructure that can be readily adopted by other investigators.
Review Criteria: Reviewers will evaluate:
Decision Support Tools and Dashboards Reviewers will evaluate:
- Interactive dashboards
- Visualization tools
- Risk prediction interfaces
- Geospatial tools
- Clinical or public health decision-support capabilities
- User experience and accessibility
Reusable Research Infrastructure
Reviewers will assess whether the project delivers reusable assets for other researchers, including:- AI-ready datasets
- APIs and MCP services
- Computational pipelines
- Notebook collections
- Python/R libraries
- Metadata templates
- Containerized workflows
- SCHARE-ready resources
Scientific Impact and Future Utility
Reviewers will evaluate the likelihood that the project will:- Accelerate AI-enabled chronic disease research
- Improve whole-person health research
- Inform intervention development
- Enable future clinical or public health applications
- Create durable infrastructure for the broader scientific community
Basis Upon Which A Winner Will Be Selected
The purpose of Phase I – IMAGINE is to identify the most innovative concepts that have the potential to transform whole-person chronic disease research by creating AI-ready datasets, advancing computational methods, and developing reusable data science infrastructure. Phase I focuses on the quality of the proposed concept, scientific vision, technical innovation, multidisciplinary expertise, and the potential to advance to a functional prototype. Applications will be evaluated by an independent panel of experts with backgrounds in chronic disease research, artificial intelligence, biomedical informatics, data science, statistics, computational biology, population health, cloud computing, and related disciplines. Participants receiving the highest overall scores on their proposals to foster big AI-ready data sets and computation methodologies to address whole-person chronic disease disparities and clearly demonstrate the likelihood of completion will be invited to participate in Phase II.
Phase I Imagine Advancement Criteria
By the end of Phase I, teams should have produced a compelling scientific and technical blueprint that clearly articulates the problem, the innovation, the data sets needed, the computational approach, and the pathway to creating reusable AI-ready data. Rather than a traditional proposal, the deliverable should function as a strategic design package that provides reviewers with confidence that the concept can mature into a transformative research resource through the subsequent prototype and validation phases.
To advance to Phase II, participants should demonstrate:
- An average score higher than 80 to be considered
- A multidisciplinary team with the expertise required to execute the project successfully.
- A compelling scientific vision with high potential for impact.
- An innovative strategy for creating AI-ready whole-person target population representative datasets.
- Novel computational methods and model features that address the dynamic nature of whole person variables to mitigate chronic disease disparities across populations and time to advance data science
- A robust framework for interoperability, AI readiness, and mechanistic discovery.
- A qualified multidisciplinary team with the expertise to execute the proposed work.
- A clear plan for developing reusable tools, workflows, and research infrastructure that can benefit the broader scientific community.
- A feasible practical plan for completion
The purpose of Phase II-BUILD is to advance their IMAGINED concept into a proof of concept demonstrating that they have access to identified data and can aggregate these fit-for-purpose data sets that can be used to address their whole-person chronic disease project. Phase II focuses on the proposed feasibility of the concept to become a functional prototype, scientific vision to address whole person chronic disease disparities, technical innovation to address data and computation/methodological challenges, and the potential to advance to a functional prototype. Applications will be evaluated by an independent panel of experts with backgrounds in chronic disease research, artificial intelligence, biomedical informatics, data science, statistics, computational biology, population health, cloud computing, and related disciplines. Participants receiving the highest overall scores on their prototypes to appropriately utilize AI-ready data sets with population representation and innovative methodological model features to address challenges and whole-person chronic disease disparities mitigation and can clearly demonstrate the likelihood of completion will be invited to participate in Phase III.
Phase II - Build Advancement Criteria
Projects advancing to Phase III should demonstrate:
- An average score higher than 85
- A fully functional prototype that creates AI-ready whole-person datasets.
- Innovative computational methods that improve data integration and mechanistic discovery.
- Interoperable workflows that can be reused across platforms and research settings.
- Practical tools (e.g., dashboards, APIs, notebooks, computational libraries) that benefit the broader scientific community.
- Evidence that the prototype is scalable, reproducible, and capable of supporting rigorous AI model development and testing.
- A clear plan for validating the prototype through benchmarking, external evaluation, and real-world model testing in Phase III.
This Phase II framework ensures the competition moves from vision (Phase I) to working infrastructure (Phase II) and sets the stage for evidence-based validation and scientific impact (Phase III).
The purpose of Phase III – PROVE is to complete the development of the Phase II product by validating its scientific, technical, and operational performance as a robust, AI-ready resource for whole-person chronic disease disparities research. Participants will demonstrate that their completed platform, dataset, computational methodology, or tool performs reliably in real-world research settings, generates trustworthy and representative AI-ready data, and advances understanding of the dynamic biological, behavioral, environmental, healthcare, community, and place-based factors that contribute to chronic disease disparities. Phase III emphasizes rigorous validation, benchmarking, reproducibility, transparency, and broad usability, while demonstrating that the final product can support mechanistic discovery, predictive modeling, intervention evaluation, and decision-making across biomedical, behavioral, healthcare, and public health applications. Applications will be evaluated by an independent panel of experts in chronic disease research, artificial intelligence, biomedical informatics, data science, computational biology, statistics, population health, and cloud computing.
Phase III Prove Success Criteria
To successfully complete the Grand Challenge, participants should demonstrate that their work has:
- At least an average score of 90
- Produced AI-ready, interoperable datasets that enable trustworthy AI research.
- Validated computational methods and AI models that outperform or complement existing approaches.
- Identified mechanistic pathways and actionable intervention opportunities that advance understanding of chronic disease.
- Demonstrated generalizable, transparent, and reproducible AI across diverse populations and settings.
- Delivered reusable dashboards, decision-support tools, APIs, workflows, and software that strengthen the research ecosystem.
- Created sustainable research infrastructure that can be integrated into SCHARE and broadly adopted to accelerate whole-person chronic disease research.
This final phase completes the progression from IMAGINE (Phase I) → BUILD (Phase II) → PROVE (Phase III), ensuring the Grand Challenge rewards not only innovation but also demonstrable scientific impact and enduring infrastructure for AI-enabled whole-person chronic disease disparities research.
Preference will be given to projects that deliver validated, interoperable, scalable, and reusable AI-ready datasets, computational models, workflows, dashboards, APIs, and software that can be integrated into SCHARE and broadly adopted by the scientific community to accelerate whole-person chronic disease disparities research.
If scores are tied, priority will be given to projects demonstrating:
- Greater potential to reduce chronic disease disparities
- Stronger integration of whole-person health concepts
- Broader scalability and public health impact
- Stronger evidence of trustworthy AI and responsible innovation
- Use of SCHARE
Phase I: Ten total prizes of $10,000 each will be awarded.
Phase II: Four total prizes of $100,000 each will be awarded
Phase III: Two total prizes – First Place $275,000 and Second Place $225,000
Award Thresholds
| Final Score | Recommendation |
|---|---|
| 94-100 | Outstanding – Strong Candidate for Winner |
| 87-93 | Excellent – Highly Competitive |
| 80-86 | Very Good – Competitive |
| 70–79 | Good |
| Below 70 | Not Competitive |
HOW TO ENTER
The official challenge announcement for the SCHARE Data Science Advance Whole-Person Data Integration and Reimagine Data Science Computations and Analytics to Address Chronic Disease Disparity Grand Challenge can be found on https://nimhd.nih.gov/resources/schare/grand-challenges/advance-whole-person-data-integration-and-analytics.
Phase 1 Submission Requirements: Each participant must submit the Challenge Registration Form to define who is participating in the Challenge and provide contact information for the Participant, and then upload the Proposal Submission on the Challenge website.
Registration Process:
All interested Participants must register and complete the form on the official challenge portal by going to https://forms.cloud.microsoft/g/Lp3sWGLj4F (when successfully submitted you will receive a response that states that “your registration was submitted”) and register for prize payment https://sam.gov/content/entity-registration by the registration deadline on 11/23/2026.
For your submission to be eligible for judging, you must:
Be eligible to compete as an Individual or as part of a Team or Entity (see Eligibility Rules). You must be a USA citizen.
For Teams: Each participating Team is required to identify a Team Leader who will register and submit on behalf of the Team members. The Team Leader is responsible for all communications with the Challenge sponsors and, in the event of winning a cash prize, the prize will be paid in full. To be eligible to receive a cash prize, the Team Leader must be a citizen of the United States. In the event that a dispute regarding the identity of the Team Leader who actually submitted the entry cannot be resolved to NIH’s satisfaction, the affected submission will be deemed ineligible.
For Entities: Each participating Entity is required to identify a Point of Contact who will register and submit on behalf of the Entity. The Point of Contact is responsible for all communications with the Challenge sponsors. In the event of winning a cash prize, the prize will be paid directly to the Entity, not to the Point of Contact. To be eligible to receive a cash prize, the Entity must be incorporated in and maintain a primary place of business in the United States. As stated in the Participation Rules, Participants intending to use Federal grant, cooperative agreement, or other transaction (OT) award funds must register for and participate in the Challenge as an Entity on behalf of the awardee institution or organization. In the event that a dispute regarding the identity of the Point of Contact who actually submitted the entry cannot be resolved to NIH’s satisfaction, the affected submission will be deemed ineligible.
The Individual, Team Leader or Point of Contact must register on the Challenge website.
Upon registering, participants will be required to identify whether they are registering as either of the following: as an individual, independent Team (i.e., registering as a group of individuals competing together but not on behalf of an established organization, institution, or corporation) or as an Entity (i.e., registering as a group of individuals competing together on behalf of a legally established organization, institution, or corporation). Participants will need to provide the name, citizenship, affiliation, and contact information of all individuals competing in this Challenge as part of a Team or on behalf of an Entity. All Participants will also be required to acknowledge whether federal funding will be used in the development of the Challenge submission (see Participation Rule 1). All Participants must certify they have read, understand, and agree to abide by the official eligibility rules, participation rules, and requirements for the Challenge as stated in this announcement.
Phase 1 – IMAGINE: Submission Process:
All interested Participants must submit required reports and files described below into the official Box folder provided after eligibility screening by the deadline on January 22, 2027.
- Phase 1 Proposal Submission
- Submissions to Phase 1 must follow the structure outlined below and adhere to the stated page limits. Do not include any proprietary or confidential information in the Title, Executive Summary, and Plain Language sections as they may be publicly shared if the participant is selected to win a prize across any phase of this Challenge (see Participation Rule 7).
- Generative Artificial Intelligence (AI) should not be used to develop the writing, imagery, or data of a submission.
- All submissions must be written in English, not AI generated, and cannot be handwritten.
- Components must not claim federal government endorsement.
- Submissions must not include the HHS’ logo or official seal or the logo of NIH or any of its components and must not claim federal government endorsement.
- Each Individual or Team may only propose 1 solution. An Entity may submit multiple entries provided there isn’t substantial overlap in team members, the team leaders are not the same, and each entry has a distinct and separate focus.
- Submissions to Phase 1 must follow the structure outlined below and adhere to the stated page limits. Do not include any proprietary or confidential information in the Title, Executive Summary, and Plain Language sections as they may be publicly shared if the participant is selected to win a prize across any phase of this Challenge (see Participation Rule 7).
- ✓ COVER PAGE (1 page)
- Submission Title
- Individual/Team/Entity Name
- Team/Entity location (City, State)
- ✓ EXECUTIVE SUMMARY (1 page): Provide a concise summary of your proposed solution, emphasizing its significance, innovation, human-relevance, and feasibility. Note that the winners’ Executive Summary section will be shared publicly.
- ✓ PLAIN LANGUAGE SUMMARY (0.5 page): Provide a summary of your submission that can be easily understood by a general audience. Describe your technical proposal in a manner that ensures the main ideas and impacts are clear and accessible to those without specialized knowledge or technical background in the field. This summary will be made public for winners and used for broader dissemination to inform the public about the will be contributions and significance of your work.
- ✓ A GRAPHICAL ABSTRACT OR SYSTEM ARCHITECTUREDIAGRAM illustrating the proposed whole-person data ecosystem and AI-ready workflow.
- ✓ INVESTIGATOR OR TEAM OR ENTITY – provide qualification and contribution of each member. Investigators should have expertise to address all aspects of the project. No more than 2 pages per key team members.
✓ PROJECT DESCRIPTION AND DATA (12 pages, including all figures, tables, and data, but excluding references. Below are suggestions for clarity)
Overview - Describe:
- The chronic disease challenge being addressed
- The research questions and intended AI applications
- The whole-person health framework
- The representation of populations for applicability
- The innovative data science or computational approach
- The anticipated impact on chronic disease research
AI-Ready Dataset Development Plan - Describe how the proposed dataset(s) will become AI-ready, including features such as:
- Data sources to be integrated
- Data harmonization strategy
- Metadata standards
- Common data elements
- Data quality assessment
- Missing-data strategy
- Population representation strategy
- Feature engineering approach
- Data governance and provenance
- AI readiness evaluation criteria
Whole-Person Data Integration Architecture - Submit a conceptual architecture illustrating features, such as: (Include the proposed interoperability strategy and data flow.)
- Biological data
- Clinical and EHR data
- Behavioral data
- Environmental exposures
- Community and geospatial data
- Non-medical drivers of health
- Other relevant data sources, including use of SCHARE data sets
Computational Innovation Plan - Describe the innovative computational methods that will be developed or adapted. Examples include: (Clearly explain why the proposed approach advances current methods)
- Data integration algorithms
- Foundation models
- Digital twins
- Synthetic data generation
- Causal inference
- Graph analytics
- Multimodal learning
- Longitudinal modeling
- Temporal modeling
- Agent-based modeling
- Bayesian approaches Privacy-preserving computation
AI Readiness Assessment Framework - Define how dataset readiness will be evaluated. The framework should address aspects, such as:
- Data completeness
- Data quality
- Interoperability
- Population representation
- Bias assessment
- Feature usability
- Metadata completeness
- Provenance
- Reproducibility
- Fitness for the intended AI application
Mechanistic Discovery Strategy - Describe how the integrated dataset and computational methods will enable researchers to identify mechanistic pathways, such as:
- Biological mechanisms
- Behavioral mechanisms
- Environmental mechanisms
- Place-based mechanisms
- Context related to living mechanisms
- Healthcare-related mechanisms
- Community-level mechanisms
- Interactions among these factors that contribute to chronic disease
- Timing of interactions among these factors that contribute to chronic disease
Impact Statement - Describe how the proposed innovation could benefit exposome research, highlight aspects such as:
- Accelerate chronic disease research
- Improve whole-person health research
- Advance AI-enabled discovery
- Increase interoperability
- Improve reproducibility
- Support future intervention development
- Produce reusable resources for the broader scientific community
Reusable Research Resource Plan - Describe the tools or resources that will ultimately be developed for the research community. Examples include:
- AI-ready datasets
- Data harmonization workflows
- Data Integration Tools
- Computational pipelines
- Interactive dashboards
- APIs / MCPs
- Python/R libraries
- Notebook collections
- Visualization tools
- Metadata templates
- SCHARE-ready resources
- ✓ COVER PAGE (1 page)
Phase 2 Eligibility:
Each participant must submit:
- Upload your responsive proposal and supporting documents in PDF or MP4 format through the designated Box Folder (provided after being deemed eligible during the registration process) by the due date July 9, 2027.
- All submissions must be written in English, not AI generated, and cannot be handwritten.
- Submissions must not include the HHS’ logo or official seal or the logo of NIH or any of its components and must not claim federal government endorsement.
- Each Phase 2 solution must be based on each Individual/Team/Entities’ respective winning Phase 1 - Imagine proposal
- Generative Artificial Intelligence (AI) should not be used to develop the writing, imagery, or data of a submission.
For your submission to be eligible for judging, you must:
- Phase I winner.
- U.S. citizen
- Be eligible to compete as an individual or as part of a Team or Entity (see Eligibility Rules).
- For Teams: Each participating Team is required to identify a Team Leader who will register and submit on behalf of the members. The Team Leader is responsible for all communications with the Challenge sponsors and, in the event of winning a cash prize, will be paid the prize in full. To be eligible to receive a cash prize, the Team Leader must be a citizen of the United States. In the event that a dispute regarding the identity of the Team Leader who actually submitted the entry cannot be resolved to NIH’s satisfaction, the affected submission will be deemed ineligible.
- For Entities: Each participating Entity is required to identify a Point of Contact who will register and submit on behalf of the Entity. The Point of Contact is responsible for all communications with the Challenge sponsors. In the event of winning a cash prize, the prize will be paid directly to the Entity, not to the Point of Contact. To be eligible to receive a cash prize, the Entity must be incorporated in and maintain a primary place of business in the United States. As stated in the Participation Rules, Participants intending to use Federal grant, cooperative agreement, or other transaction (OT) award funds must register for and participate in the Challenge as an Entity on behalf of the awardee institution or organization. In the event that a dispute regarding the identity of the Point of Contact who actually submitted the entry cannot be resolved to NIH’s satisfaction, the affected submission will be deemed ineligible.
- The Team Leader or Point of Contact:
- Complete and submit the Registration Form if applicable https://forms.cloud.microsoft/g/Lp3sWGLj4F. If any member of Phase I team/entity changed, solvers will be required to fill in an Eligibility Review Form and answer multiple questions to determine the eligibility of the Team/Entity submitting, as well as confirmation that the Team/Entity meets and accepts all rules to participate in the challenge. If there are no team/entity changes, there is no need to register again.
- Each Phase 2 solution must be based on each Team/Entities’ respective Phase 1 submission.
- All submissions must be written in English and cannot be handwritten.
- Submissions must not include the HHS’ logo or official seal or the logo of NIH or any of its components and must not claim federal government endorsement.
- Generative Artificial Intelligence (AI) should not be used to develop the writing, imagery, or data of a submission.
Phase 2 Milestone 1 Proposal Submission
- Submissions to Phase 2 Milestone 1 must follow the structure outlined below and adhere to the stated page limits. Do not include any proprietary or confidential information in the Title, Executive Summary, and Plain Language sections as they may be publicly shared if the participant is selected to win a prize across any phase of this Challenge (see Participation Rule 7)
- Requirements:
- ✓ OVERVIEW – Summary of Project in plain English and Investigators roles (1 page) - Any adaptation or change in status – design or team/entity members
- ✓ WORKFLOW DEMONSTRATION - Demonstrate the complete computational workflow. (1 page) For example:
Raw data
↓
Integration
↓
Cleaning
↓
Harmonization
↓
Feature engineering
↓
Metadata generation
↓
AI-ready dataset
↓
Visualization
↓
- Export
✓ TECHNICAL PACKAGE (up to 15 pages) Address the following categories:
Functional Prototype - Develop a working prototype demonstrating:
- automated data ingestion
- interoperability across multiple data sources
- harmonization workflows
- metadata generation
- AI-ready dataset creation
- reusable computational workflows
AI-Ready Whole-Person Dataset - Datasets should be reusable by other investigators. Produce one or more datasets that demonstrate:
- interoperability
- AI readiness
- metadata completeness
- provenance
- data quality
- population representation
- scalability
- reusable feature engineering
- standardized common data elements
- documentation, including data dictionary
Interoperable Computational Workflows - Workflows should be reproducible and portable. Provide documented workflows for:
- data integration
- data harmonization
- feature engineering
- missing-data handling
- synthetic data generation (if applicable)
- quality assessment
- metadata generation
- AI-ready dataset preparation
Computational Innovation and Mechanistic Discovery Capability - These features should address the dynamic synergistic or antagonistic relationship of whole person health.
- Computational Innovation Demonstration - Demonstrate how these methods improve current approaches. Develop and demonstrate one or more innovative computational methods. Examples include:
- multimodal AI
- graph learning
- causal inference
- digital twins
- temporal analytics
- Bayesian learning
- longitudinal modeling
- privacy-preserving computation
- explainable AI
- Mechanistic Discovery Prototype - The prototype should illustrate how these methods generate hypotheses or identify potential intervention targets. Demonstrate computational approaches capable of identifying mechanistic pathways associated with chronic disease, including factors such as:
- biological pathways
- behavioral pathways
- environmental pathways
- non-medical drivers of health pathways
- contextual social influences
- healthcare-related pathways
- community interactions
- temporal relationships
- potential intervention targets
Research Utility, Reusability, and Implementation
- Reusable Research Resources – Examples include
- dashboards
- APIs
- computational libraries
- notebook collections
- software
- reusable workflows
- metadata templates
- reusable workflows
- MCP services
- Notebooks
- Workflow templates
- Docker containers
- Cloud workflows
- metadata templates
- SCHARE-ready resources
- Visualization, Dashboards, and User Experience – Examples include
- usability
- intuitive design
- scientific visualization
- researcher accessibility
- decision-support capability
- Scalability, Reproducibility, and Documentation
- documentation quality plan
- reproducibility
- portability
- scalability
- technical transparency
- ease of implementation
- ✓ DEVELOPMENT PLAN (up to 5 pages, spreadsheet Gantt timeline), Validation Report - Include evidence that the prototype will work. Examples:
- Data quality metrics
- Processing time
- Scalability testing
- Interoperability testing
- Reproducibility testing
- Benchmark comparisons
- User testing (if applicable)
- ✓ SOLUTION DEMONSTRATION (up to one 15-minute video)
Phase 3 Submission Requirements:
Each participant must submit:
- Complete and submit the Registration Form https://forms.cloud.microsoft/g/Lp3sWGLj4F within 30 days of notification if applicable. If any member of Phase I team/entity changed, solvers will be required to fill in an Eligibility Review Form, answer multiple questions to determine the eligibility of the Team/Entity submitting, as well as confirmation that the Team/Entity meets and accepts all rules to participate in the challenge. If there are no team/entity changes, there is no need to register again.
- Upload your responsive Proposal and supporting documents in PDF or MP4 format through the designated Box Folder (provided to you after being deemed eligible during the registration process) by the due date November 19, 2027.
- All submissions must be written in English and cannot be handwritten.
- Submissions must not include the HHS’ logo or official seal or the logo of NIH or any of its components and must not claim federal government endorsement.
- Each Phase 3 solution must be based on each Individual/Team/Entities’ respective winning Phase 2 - Build proposal
- Generative Artificial Intelligence (AI) should not be used to develop the writing, imagery, or data of a submission.
Since the goal of the Grand Challenge is to build AI infrastructure capacity for whole-person (exposome) chronic disease research, the final submissions should include validated datasets, tested computational tools, reusable software, decision-support resources, and evidence that the infrastructure improves AI-driven research for chronic disease disparities mitigation or knowledge generation.
Submission Requirements:
- ✓ OVERVIEW – Summary of Project in plain English and Investigators roles (1 page) - Any adaptation or change in status – design or team/entity members
- ✓ WORKFLOW DEMONSTRATION (end to end)
- ✓ DASHBOARD OR TOOL DEMONSTRATION
✓ AI MODEL PERFORMANCE AND VALIDATION
Validated AI-Ready Dataset(s) (Required) - Submit one or more finalized datasets that have been: These datasets should be reusable by other investigators.
- Fully harmonized and integrated
- AI-ready and fit-for-purpose
- Tested for completeness and quality
- Evaluated for population representation
- Documented with metadata and provenance
- Accompanied by a data dictionary and common data elements
Validated AI Models - Submit one or more validated AI or machine learning models demonstrating the use of the infrastructure. Examples include:
- Risk prediction
- Disease progression
- Phenotype identification
- Early disease detection
- Treatment response prediction
- Causal models
- Survival models
Include:
- Model documentation including model cards
- Training/testing methodology
- Performance metrics
- External validation results
- Explainability outputs
Benchmark Performance Report
- Explain how this tool outperforms existing tools
- Provide Performance Metrics, such as:
- AUROC
- Precision
- Recall
- Calibration
- Sensitivity
- Specificity
- F1 score
- Clinical utility
- Computational efficiency
✓ SCIENTIFIC DISCOVERY AND MECHANISTIC INSIGHTS
Mechanistic Discovery Report - Provide evidence showing how the integrated data and computational methods identified mechanisms contributing to chronic disease. The report should describe why these mechanisms are scientifically important and how they inform prevention or intervention strategies.
Examples:
- Biological pathways
- Environmental pathways
- Behavioral pathways
- Non-medical drivers of health pathways
- Contextual factors
- Healthcare system pathways
- Community-level interactions
- Temporal relationships
✓ GENERALIZABILITY AND POPULATION PERFORMANCE - Demonstrate model performance across:
- Age groups
- Sex
- Geography
- Socioeconomic contexts
- Underrepresented populations
- Disease severity
- Healthcare settings
Describe strategies used to evaluate:
- Population representation
- External validation
- Transferability
- Model robustness
✓ COMPUTATIONAL INNOVATION, TRANSPARENCY AND TRUST -
Demonstrate computational approaches that identify knowledge to mitigate chronic disease disparities – innovative methodologies examples:
- Responsible AI and Model Transparency
- Explainability
- Bias assessment
- Reproducibility
- Uncertainty quantification
- Documentation
- Model interpretability
- Privacy protection
- Computational Innovation (examples)
- Novel computational methods
- Advancement beyond existing approaches
- Scalability
- Efficiency
- Reusability
- multi-domain interactions
- temporal interactions
- synergistic or antagonistic
- Responsible AI and Model Transparency
✓ RESEARCH TRANSLATION, UTILITY, AND SCIENTIFIC IMPACT
Address these elements as appropriate:
- Decision Support Tools and Dashboards
- Interactive dashboards
- Visualization tools
- Risk prediction interfaces
- Geospatial tools
- Clinical or public health decision-support capabilities
- User experience and accessibility
- Reusable Research Infrastructure
- AI-ready datasets
- APIs and MCP services
- Computational pipelines
- Notebook collections
- Python/R libraries
- Metadata templates
- Containerized workflows
- SCHARE-ready resources
- Scientific Impact and Future Utility
- Accelerate AI-enabled chronic disease research
- Improve whole-person health research
- Inform intervention development
- Enable future clinical or public health applications
- Create durable infrastructure for the broader scientific community
- Research applications
- Decision Support Tools and Dashboards
RULES
To be eligible to win a prize under this Challenge, a Participant (whether participating as a Team or Entity):
- Shall have registered to participate in the Challenge under the rules promulgated by the National Institutes of Health (NIH) as published in this announcement;
- Shall have complied with all the requirements set forth in this announcement;
- In the case of a private entity, shall be incorporated in and maintain a primary place of business in the United States, and in the case of an individual, whether participating singly or in a group, shall be a citizen of the United States. However, non-U.S. citizens and non-permanent residents can participate as a member of a team that otherwise satisfies the eligibility criteria. Non-U.S. citizens and non-permanent residents are not eligible to win a monetary prize (in whole or in part). Their participation as part of a winning team, if applicable, may be recognized when the results are announced.
- Shall not be a federal entity or federal employee acting within the scope of their employment;
- Shall not be an employee of the Department of Health and Human Services (HHS, or any other component of HHS) acting in their personal capacity;
- Who is employed by a federal agency or entity other than HHS (or any component of HHS), should consult with an agency ethics official to determine whether the federal ethics rules will limit or prohibit the acceptance of a prize under this Challenge;
- Shall not be a judge of the Challenge, or any other party involved with the design, production, execution, or distribution of the Challenge or the immediate family of such a party (i.e., spouse, parent, step-parent, child, or step-child).
- Shall be 18 years of age or older at the time of submission.
- Federal grantees and recipients of cooperative agreements or other transaction (OT) awards are eligible to participate in the Challenge but may not use Federal funds from a grant award, cooperative agreement, or OT award to develop their Challenge submission or to fund efforts in support of their Challenge submission unless use of such funds is consistent with the purpose, terms, and conditions of the grant award, cooperative agreement, or OT award. Each Participant intending to use Federal grant, cooperative agreement, or OT award funds must register for and participate in the Challenge as an entity on behalf of the awardee institution, organization, or entity. If a winning Participant uses Federal grant, cooperative agreement, or OT award funds to participate in the Challenge, the prize must be treated as program income for purposes of the original grant, cooperative agreement, or OT award in accordance with applicable Uniform Administrative Requirements, Cost Principles, and Audit Requirements for Federal Awards [2 CFR § 200]. Participants using Federal grant, cooperative agreement, or OT award funds to participate and/or report prize funding as program income (for winning Participants) should coordinate with the awarding official at the federal awarding agency.
- Federal contractors may not use federal funds from a contract to develop their Challenge submissions or to fund efforts in support of their Challenge submissions.
- By participating in this Challenge, each Participant (whether participating as an Individual or as a Team or Entity) agrees to assume any and all risks and waive claims against the federal government and its related entities, except in the case of willful misconduct, for any injury, death, damage, or loss of property, revenue, or profits, whether direct, indirect, or consequential, arising from participation in this Challenge, whether the injury, death, damage, or loss arises through negligence or otherwise.
- By participating in this Challenge, each Participant (whether participating as an Individual or as a Team or Entity) agrees Generative Artificial Intelligence (AI) should not be used to develop the writing, imagery, or data of a submission.
- Based on the subject matter of the Challenge, the type of work that it will possibly require, as well as an analysis of the likelihood of any claims for death, bodily injury, property damage, or loss potentially resulting from Challenge participation, no Participant (whether participating as an Individual or as a Team or Entity) participating in the Challenge is required to obtain liability insurance, or demonstrate financial responsibility, or agree to indemnify the federal government against third party claims for damages arising from or related to Challenge activities in order to participate in this Challenge.
- A Participant (whether participating as an Individual or as a Team or Entity) shall not be deemed ineligible because the Participant used federal facilities or consulted with federal employees during the Challenge if the facilities and employees are made available to all Participants participating in the Challenge on an equitable basis.
- By participating in this Challenge, each Participant (whether participating as an Individual or as a Team or Entity) warrants that they are sole author or owner of, or has the right to use, any copyrightable works that the submission comprises, that the works are wholly original with the Participant (or is an improved version of an existing work that the Participant has sufficient rights to use and improve), and that the submission does not infringe any copyright or any other rights of any third party of which the Participant is aware.
- By participating in this Challenge, each Participant (whether participating as an Individual or as a Team or Entity) grants to the NIH an irrevocable, paid-up, royalty-free nonexclusive worldwide license to reproduce, publish, post, link to, share, and display publicly the submission on the web or elsewhere. Each Participant will retain all other intellectual property rights in their submissions, as applicable. To participate in the Challenge, each Participant must warrant that there are no legal obstacles to providing the above-referenced nonexclusive licenses of the Participant’s rights to the federal government. To receive an award, Participants will not be required to transfer their intellectual property rights to NIH, but Participants must grant to the federal government the nonexclusive licenses recited herein.
- Each Participant (whether participating as an Individual or as a Team or Entity) agrees to follow all applicable federal, state, and local laws, regulations, and policies.
- Each Participant (whether participating as an Individual or as a Team or Entity) participating in this Challenge must comply with all terms and conditions of these rules, and participation in this Challenge constitutes each such Participant’s full and unconditional agreement to abide by these rules. Winning is contingent upon fulfilling all requirements herein.
- As a condition for winning a cash prize in this Challenge, each Participant (whether participating as an Individual or as a Team or Entity) that has been selected as a winner must complete and submit all requested winner verification and payment documents to NIH within 10 business days of formal notification. Failure to return all required verification documents by the date specified in the notification may be a basis for disqualification of a cash prize winning submission.
Disqualification
Submissions may be disqualified for plagiarism, falsification of any information submitted, use of copyrighted material without permission, and use of profanity, violent images, or nudity. NIMHD is not responsible for lost, late, incomplete, invalid, unintelligible, or misdirected entries, which will be disqualified.
Award Approving Official
The Award Approving Official will be Monica Webb Hooper, PhD, (Acting) Director of the National Institute on Minority Health and Health Disparities, or as otherwise delegated.
Payment of the Prize
Prizes awarded under this Challenge will be paid by electronic funds transfer and may be subject to federal income taxes. The Department of Health and Human Services (HHS)/NIH will comply with the Internal Revenue Service withholding and reporting requirements, where applicable. Entities participating in this Challenge are encouraged, but not required, to request and obtain a free Unique Entity ID (UEI), if they have not already done so, via SAM.gov as this will expedite prize payment. Additional information can be found at https://sam.gov/content/entity-registration.
NIH/NIMHD reserves the right, in its sole discretion, to (a) cancel, suspend, or modify the Challenge, or any part of it, for any reason, and/or (b) not award any prizes if no submissions are deemed worthy.
Legal and Participation Terms
Participation in this Challenge does not create a clinician-patient relationship, and content shared on the platform does not constitute medical advice, diagnosis, treatment, guidance, or instruction regarding any disease or health condition. Participants should consult qualified healthcare professionals regarding personal medical decisions or health conditions.
The views expressed by participants do not necessarily reflect those of the HHS, NIH, NIMHD or the federal government.
ADDITIONAL INFORMATION
Questions? Email SCHAREChallenges.nih.gov
Challenge Manager
Deborah Duran, PhD
Point of contact email
durande@nih.gov
Resources
SCHARE (Science Collaborative for Health and AI Reduction of Errors)